
We have been working closely with the CMS physics group at Notre Dame for the last year to build
Lobster, a data analysis system that runs on O(10K) cores to process data produced by the
CMS experiment at the
LHC. At peak, Lobster at ND delivers capacity equal to that of a dedicated CMS Tier-2 facility!
Existing data analysis systems for CMS generally require that the user be running in a cluster that has been set up
just so for the purpose: exactly the right operating system, certain software installed, various user identities present, and so on. This is fine for the various clusters dedicated to the CMS experiment, but it leaves unused the enormous amount of computing power that can be found at university computing centers (like the
ND CRC), national computing resources (like
XSEDE or the
Open Science Grid), and public cloud systems.
Lobster is designed to harness clusters that are not dedicated to CMS. This requires solving two problems:
- The required software and data are not available on every node. Instead, Lobster must bring them in at runtime and create the necessary execution system on the fly.
- A given machine may only be available for a short interval of time before it is taken away and assigned to another user, so Lobster must be efficient at getting things set up, and handy at dealing with disconnections and failures.
To do this, we build upon a variety of technologies for distributed computing. Lobster uses
Work Queue to dispatch tasks to thousands of machines,
Parrot with
CVMFS to deliver the complex software stack from CERN,
XRootD to deliver the LHC data, and
Chirp and
Hadoop to manage the output data.
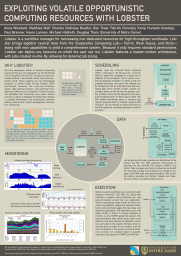
Lobster runs effectively on O(10K) cores so far, depending on the CPU/IO ratio of the jobs. These two graphs show the behavior of a production run on top of
HTCondor at Notre Dame hitting up to 10K cores over the course of a 48-hour run. The top graph shows the number of tasks running simultaneously, while the bottom shows the number of tasks completed or failed in each 10-minute interval. Note that about two thirds of the way through, there is a big hiccup, due to an external network outages. Lobster accepts the failures and keeps on going.
Lobster has been a team effort between Physics, Computer Science, and the Center for Research Computing: Anna Woodard and Matthias Wolf have taken the lead in developing the core software; Ben Tovar, Patrick Donnelly, and Peter Ivie have improved and debugged Work Queue, Parrot, and Chirp along the way; Charles Mueller, Nil Valls, Kenyi Anampa, and Paul Brenner have all worked to deploy the system at scale in production; Kevin Lannon, Michael Hildreth, and Douglas Thain provide the project leadership.
| Anna Woodard, Matthias Wolf, Charles Nicholas Mueller, Ben Tovar,
Patrick Donnelly, Kenyi Hurtado Anampa, Paul Brenner, Kevin Lannon, and
Michael Hildreth, Exploiting Volatile Opportunistic Computing Resources with Lobster, Computing in High Energy Physics, January, 2015. |
|
Anna Woodard, Matthias Wolf, Charles Mueller, Nil Valls, Ben Tovar,
Patrick Donnelly, Peter Ivie, Kenyi Hurtado Anampa, Paul Brenner,
Douglas Thain, Kevin Lannon and Michael Hildreth, Scaling Data Intensive Physics Applications to 10k Cores on Non-Dedicated Clusters with Lobster, IEEE Conference on Cluster Computing, September, 2015.
|


